Edge0-145B (latent MoE)
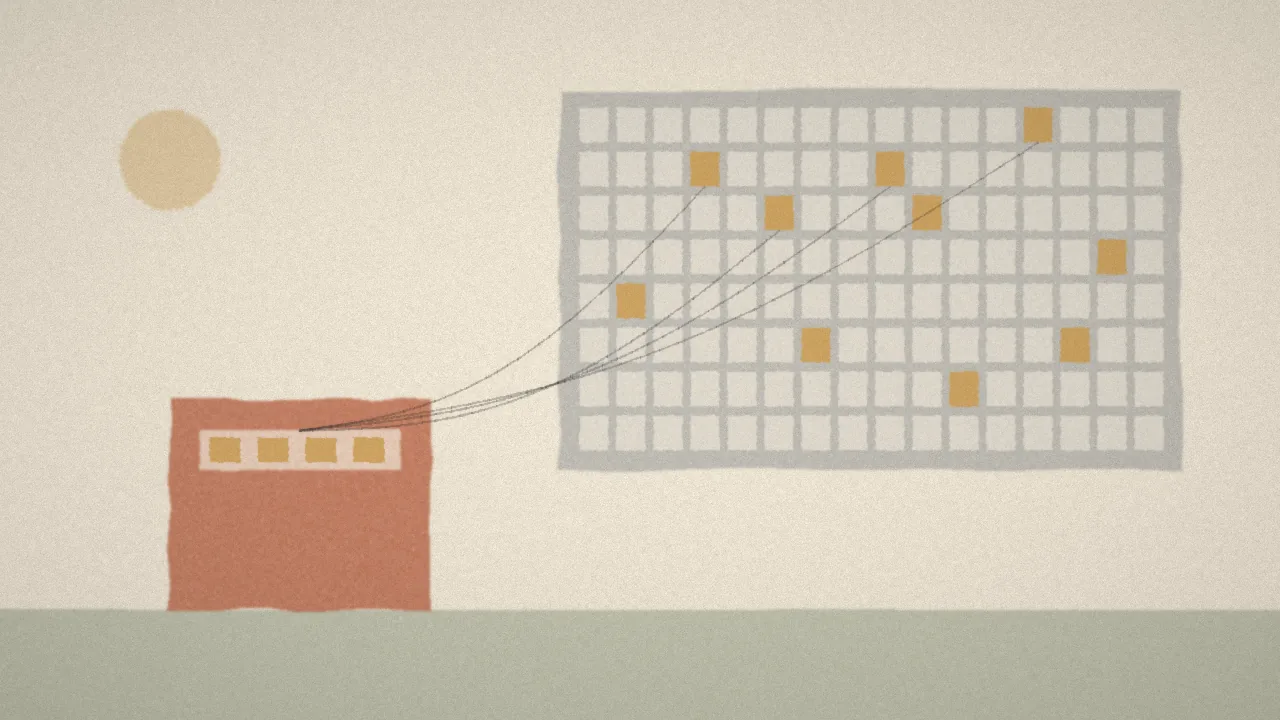
Open-weight 145B agent model that rebuilds Qwen3.8-Flash-Next with smaller latent experts so an engine can keep hot experts on one consumer GPU and stream the rest from RAM. Edge0 reports 121.2 tok/s (Q3_K) / 98.3 tok/s (NVFP4) agent decode on an RTX 5090 D, 86.5 on Terminal-Bench 2.1 and 64.6 on DeepSWE 1.1 (vendor-reported).
Interactive Token Cost Estimator (Edge0-145B)
GPU Hardware Compatibility Matrix (Edge0-145B at 16K Context)
| GPU / Hardware Profile | VRAM | Q4_K_M (4.8-bit) | Q8_0 (8-bit) | Est. Speed (Q4) |
|---|---|---|---|---|
| RTX 5060 Ti 16GB 448 GB/s | 16 GB | REQUIRES MULTI-GPU (89.31 GB) | REQUIRES MULTI-GPU (156.03 GB) | ~10 tok/s |
| RTX 4090 24GB 1008 GB/s | 24 GB | REQUIRES MULTI-GPU (89.31 GB) | REQUIRES MULTI-GPU (156.03 GB) | ~23 tok/s |
| RTX 5090 32GB 1792 GB/s | 32 GB | REQUIRES MULTI-GPU (89.31 GB) | REQUIRES MULTI-GPU (156.03 GB) | ~41 tok/s |
| M4 Max 64GB 546 GB/s | 52 GB | REQUIRES MULTI-GPU (89.31 GB) | REQUIRES MULTI-GPU (156.03 GB) | ~13 tok/s |
| 2× 24GB (48GB) 920 GB/s | 48 GB | REQUIRES MULTI-GPU (89.31 GB) | REQUIRES MULTI-GPU (156.03 GB) | ~21 tok/s |
| H100 80GB 3350 GB/s | 80 GB | REQUIRES MULTI-GPU (89.31 GB) | REQUIRES MULTI-GPU (156.03 GB) | ~77 tok/s |
| M4 Ultra 192GB 819 GB/s | 164 GB | FITS IN VRAM (89.31 GB) | TIGHT FIT (Q8 KV) (156.03 GB) | ~88 tok/s |
| 8× H200 (1,128GB) 4800 GB/s | 1128 GB | FITS IN VRAM (89.31 GB) | FITS IN VRAM (156.03 GB) | ~518 tok/s |
Architectural Strengths & Target Workloads
- 145B-class quality at ~10B active parameters, designed for single-GPU expert streaming
- Vendor-reported 86.5 Terminal-Bench 2.1 and 64.6 DeepSWE 1.1, ahead of its Qwen base
- OpenAI- and Anthropic-compatible local server; vision encoder included
Primary Engineering Workloads: Local Agentic Coding · Private / Offline Executor Model · Single-Workstation Inference.
Frequently Asked Questions (Edge0-145B)
How much does Edge0-145B (latent MoE) cost per 1M tokens?
Edge0-145B (latent MoE) is priced at $0.00 per 1M uncached input tokens, $0.00 per 1M cached input tokens, and $0.00 per 1M output tokens (Self-hosted only via edge0-infer (OpenAI- and Anthropic-compatible endpoints) or the Edge0 Chat Windows app; no hosted inference provider at launch).
What is the context window of Edge0-145B (latent MoE)?
It supports up to 256K tokens (KV int8, 32K resident) (262,144 tokens) and a maximum generation output of 32,768 tokens.
Edge0-145B: An Open-Weight 145B Agent Model That Runs on One 24 GB GPU by Streaming Its Experts
Edge0 rebuilt Qwen3.8-Flash-Next's mixture-of-experts layer so each expert works in a smaller latent space and takes up a fixed 1.63 MB. Its engine keeps the experts it uses most on the GPU and streams the rest from system RAM. On an RTX 5090 D, Edge0 reports 98 to 121 tok/s for agent decoding and 86.5 on Terminal-Bench 2.1. The license limits commercial use.
Read Full Technical Dispatch (5 min read) →